2026
On the Generalization Limitation of On-Policy Distillation for Post-RL Consolidation
Yichen Wang, Yufa Zhou, Siqi Zhu, Haozheng Luo, Jingzhi Bao, Zhichao Liu, Zijun Wei
arXiv 2026
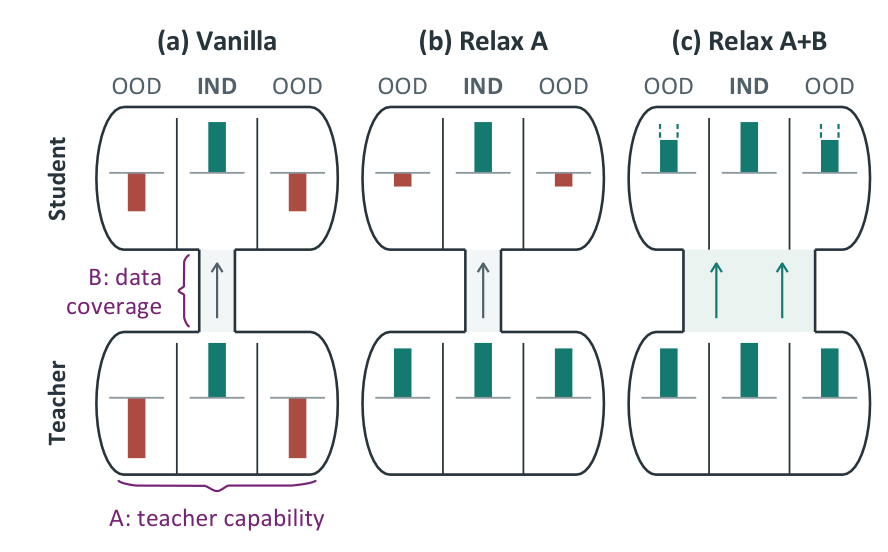
We show that near-perfect in-distribution on-policy distillation from one or more RL-trained teachers can mask incomplete capability consolidation out of distribution, identify teacher capability and data coverage as the two bottlenecks, and propose geometry-based patching and base-preserving replay to improve out-of-distribution retention.
On the Generalization Limitation of On-Policy Distillation for Post-RL Consolidation
Yichen Wang, Yufa Zhou, Siqi Zhu, Haozheng Luo, Jingzhi Bao, Zhichao Liu, Zijun Wei
arXiv 2026
We show that near-perfect in-distribution on-policy distillation from one or more RL-trained teachers can mask incomplete capability consolidation out of distribution, identify teacher capability and data coverage as the two bottlenecks, and propose geometry-based patching and base-preserving replay to improve out-of-distribution retention.
On the Origin and Evolution of Training-Inference Mismatch in LLM Reinforcement Learning
Yu Li*, Yufa Zhou*, Tian Lan(* equal contribution)
arXiv 2026
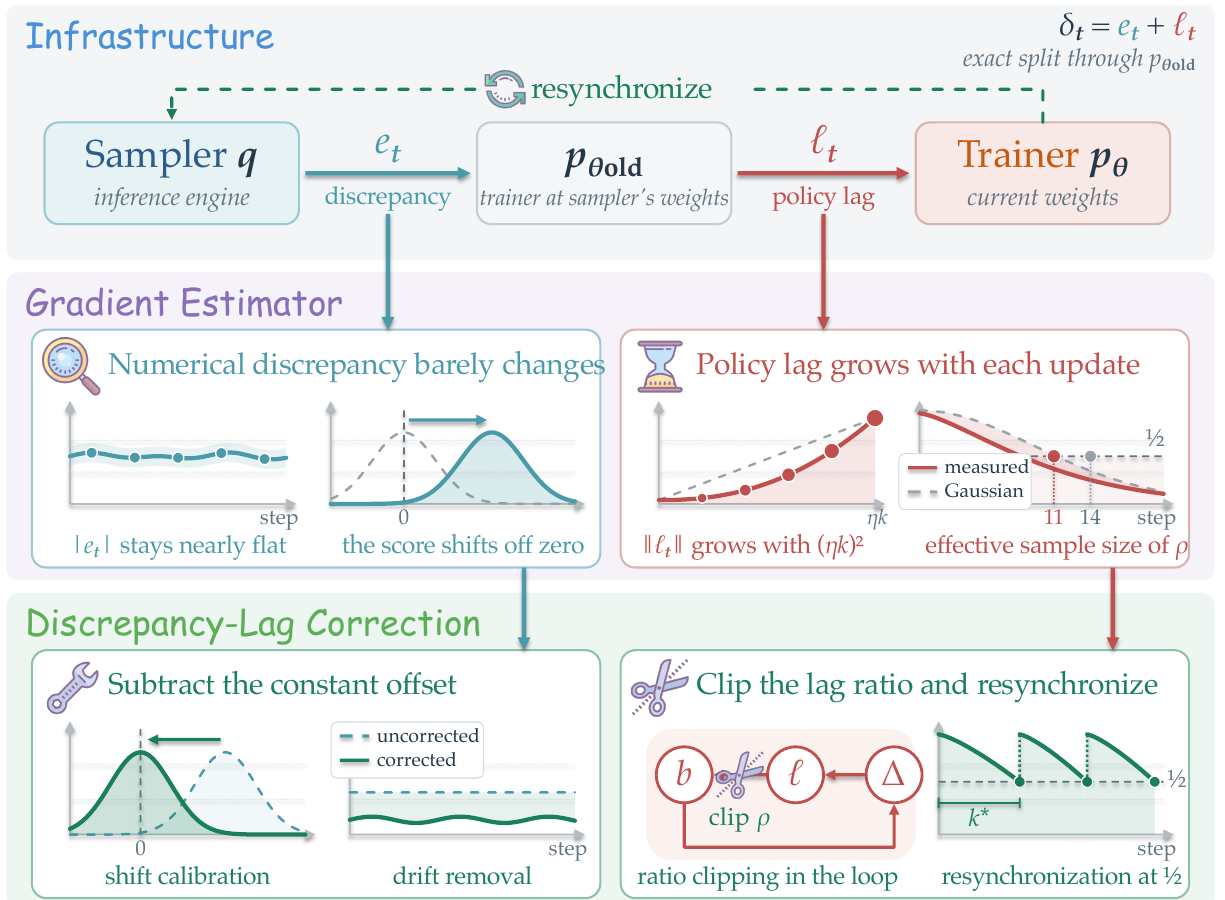
We split the training-inference mismatch in LLM reinforcement learning exactly into a near-constant numerical discrepancy and a self-reinforcing policy lag, and derive the discrepancy-lag correction (DLC), which centers the former, clips the latter, and resynchronizes the sampler when the effective sample size of the lag ratio falls below one half.
On the Origin and Evolution of Training-Inference Mismatch in LLM Reinforcement Learning
Yu Li*, Yufa Zhou*, Tian Lan(* equal contribution)
arXiv 2026
We split the training-inference mismatch in LLM reinforcement learning exactly into a near-constant numerical discrepancy and a self-reinforcing policy lag, and derive the discrepancy-lag correction (DLC), which centers the former, clips the latter, and resynchronizes the sampler when the effective sample size of the lag ratio falls below one half.
Athanor: An Agent-Native System for Autonomous Post-Training Research
Yufa Zhou, Yichen Wang, Jiakun Fan, Ziqi Shu, Zhichao Liu, Anru R. Zhang, Neiwen Ling, Zijun Wei
arXiv 2026
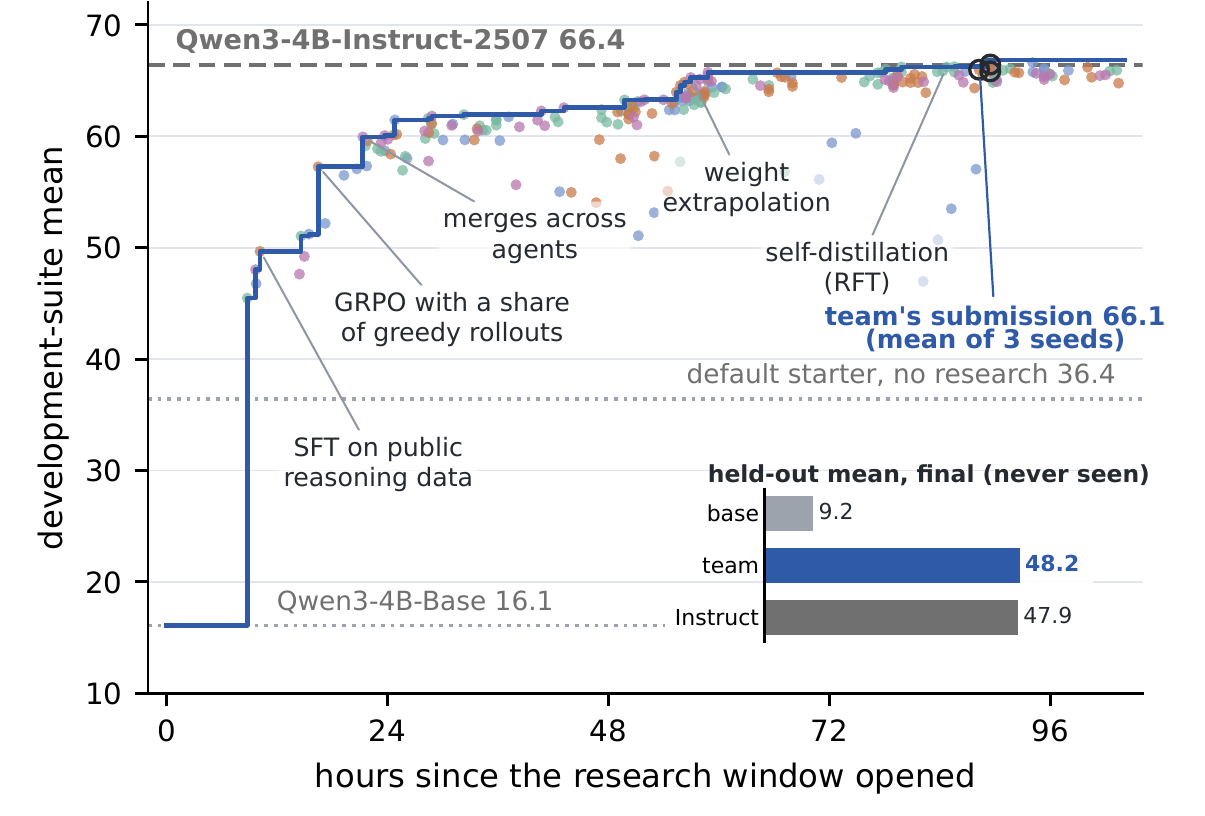
We build Athanor, an agent-native system for post-training research, and show that a team of four frontier agents, with no teacher model or human advice, autonomously post-trains Qwen3-4B-Base to match the official instruct model, including on a held-out suite the agents never see.
Athanor: An Agent-Native System for Autonomous Post-Training Research
Yufa Zhou, Yichen Wang, Jiakun Fan, Ziqi Shu, Zhichao Liu, Anru R. Zhang, Neiwen Ling, Zijun Wei
arXiv 2026
We build Athanor, an agent-native system for post-training research, and show that a team of four frontier agents, with no teacher model or human advice, autonomously post-trains Qwen3-4B-Base to match the official instruct model, including on a held-out suite the agents never see.
The Geometry of Contextual Relations: Language Models Address Facts by Order of Mention
Yufa Zhou
arXiv 2026
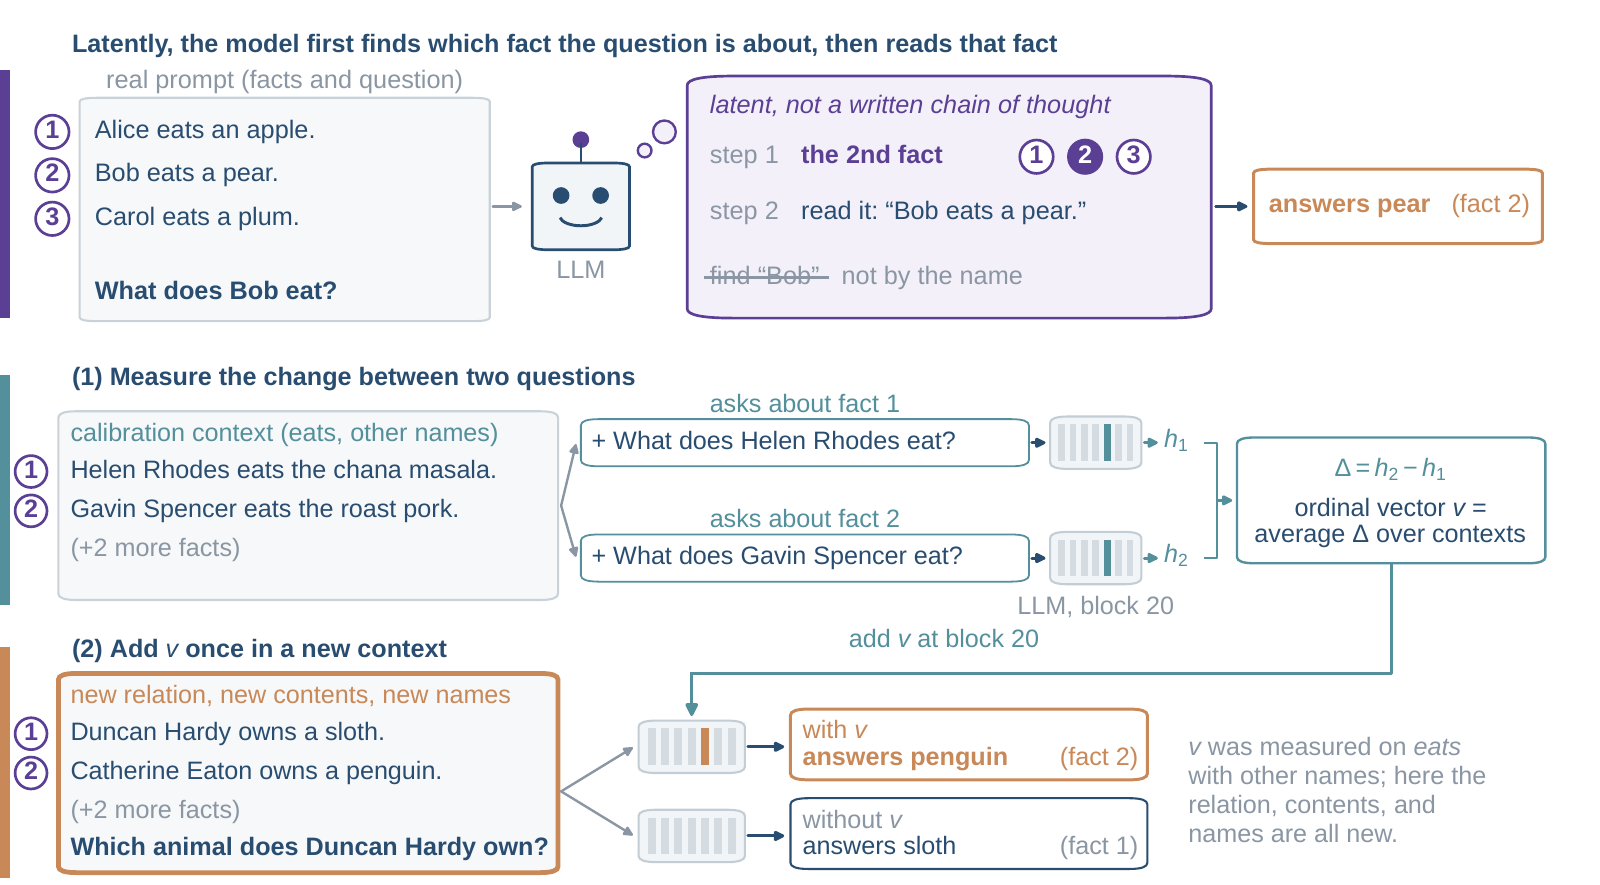
We show that LLMs reach an in-context fact by its order of mention, not by the name in the question: a shared, steerable, low-rank subspace of fact addresses, found across 14 models from 1.5B to 32B parameters and formed early in pretraining, lets a question point to the fact it asks about while the context supplies what that fact says.
The Geometry of Contextual Relations: Language Models Address Facts by Order of Mention
Yufa Zhou
arXiv 2026
We show that LLMs reach an in-context fact by its order of mention, not by the name in the question: a shared, steerable, low-rank subspace of fact addresses, found across 14 models from 1.5B to 32B parameters and formed early in pretraining, lets a question point to the fact it asks about while the context supplies what that fact says.
DraftAttention2: Fast Video Diffusion with Low-Resolution-Guided Mixed-Precision Attention
Rui Ding, Haopeng Li, Weize Ma, Yufa Zhou, Yitong Li, Xiaoling Zhou, Jiashuo Cao, Liyang Li, Hua Geng, Jiuxiang Gu, Jun Lin, Enze Xie, Xuan Shen
arXiv 2026
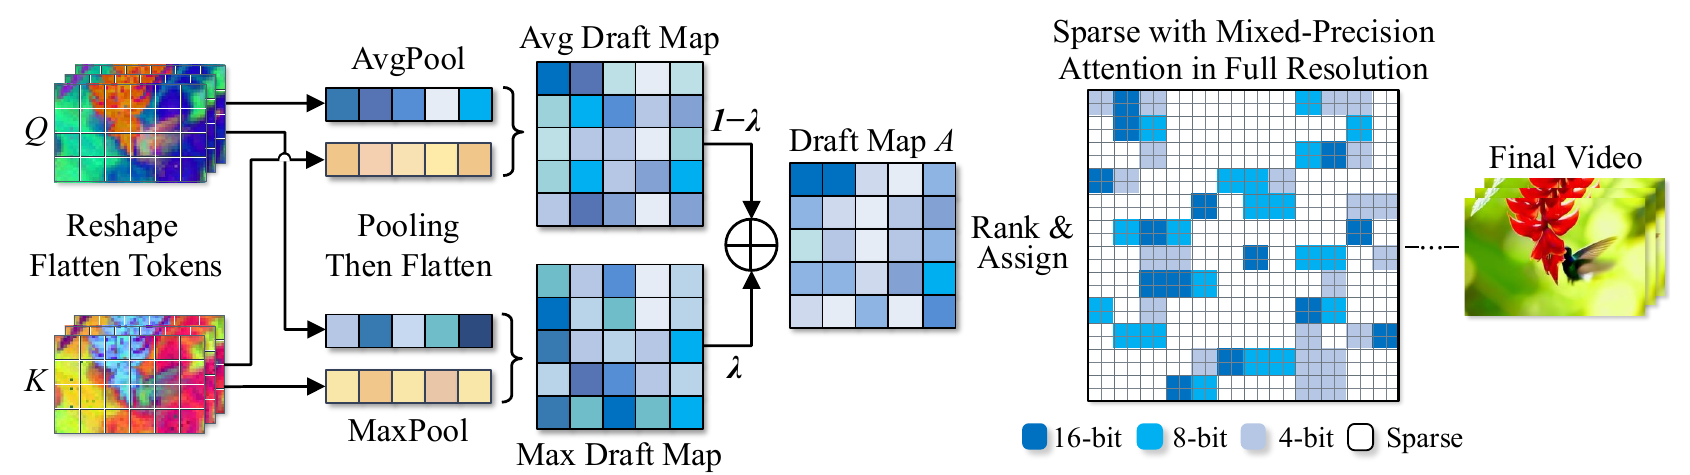
We present DraftAttention2, a training-free method that uses a low-resolution draft attention map to sparsify attention blocks and assign mixed precision, improving the quality-efficiency trade-off for video diffusion, especially in the few-step setting.
DraftAttention2: Fast Video Diffusion with Low-Resolution-Guided Mixed-Precision Attention
Rui Ding, Haopeng Li, Weize Ma, Yufa Zhou, Yitong Li, Xiaoling Zhou, Jiashuo Cao, Liyang Li, Hua Geng, Jiuxiang Gu, Jun Lin, Enze Xie, Xuan Shen
arXiv 2026
We present DraftAttention2, a training-free method that uses a low-resolution draft attention map to sparsify attention blocks and assign mixed precision, improving the quality-efficiency trade-off for video diffusion, especially in the few-step setting.
Simple KNN-Based Outlier Detection Achieves Robust Clustering
Tianle Jiang*, Yufa Zhou*(α–β alphabetical order)
NeurIPS 2026
We show that a simple KNN-based outlier detection method achieves efficient and accurate robust clustering by removing points with large K-nearest-neighbor distances, attaining approximation guarantees comparable to prior work and strong empirical performance.
Simple KNN-Based Outlier Detection Achieves Robust Clustering
Tianle Jiang*, Yufa Zhou*(α–β alphabetical order)
NeurIPS 2026
We show that a simple KNN-based outlier detection method achieves efficient and accurate robust clustering by removing points with large K-nearest-neighbor distances, attaining approximation guarantees comparable to prior work and strong empirical performance.

Efficient Reasoning with Hidden Thinking
Xuan Shen, Yizhou Wang, Yufa Zhou, Xiangxi Shi, Pu Zhao, Yanzhi Wang, Jiuxiang Gu
ICML 2026
We propose Heima, an efficient reasoning framework that performs Chain-of-Thought reasoning in hidden latent space by condensing intermediate reasoning steps into compact thinking tokens, substantially reducing reasoning verbosity while maintaining or improving zero-shot accuracy across multimodal reasoning benchmarks.
Efficient Reasoning with Hidden Thinking
Xuan Shen, Yizhou Wang, Yufa Zhou, Xiangxi Shi, Pu Zhao, Yanzhi Wang, Jiuxiang Gu
ICML 2026
We propose Heima, an efficient reasoning framework that performs Chain-of-Thought reasoning in hidden latent space by condensing intermediate reasoning steps into compact thinking tokens, substantially reducing reasoning verbosity while maintaining or improving zero-shot accuracy across multimodal reasoning benchmarks.
Grounding and Enhancing Informativeness and Utility in Dataset Distillation
Shaobo Wang, Yantai Yang, Guo Chen, Peiru Li, Kaixin Li, Yufa Zhou, Zhaorun Chen, Linfeng Zhang
ICLR 2026
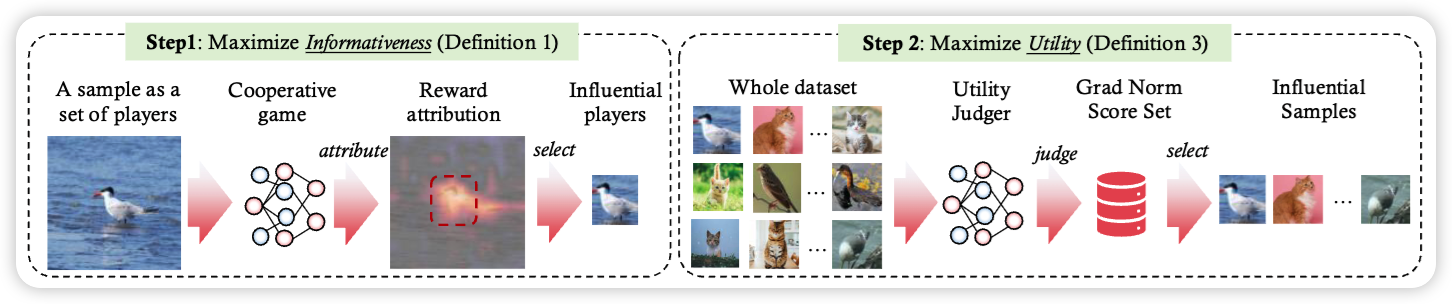
We propose InfoUtil, a principled dataset distillation framework that formalizes informativeness and utility, leveraging Shapley value attribution and gradient-norm-based selection to synthesize compact yet highly effective datasets, achieving consistent SOTA performance and efficiency across architectures and benchmarks.
Grounding and Enhancing Informativeness and Utility in Dataset Distillation
Shaobo Wang, Yantai Yang, Guo Chen, Peiru Li, Kaixin Li, Yufa Zhou, Zhaorun Chen, Linfeng Zhang
ICLR 2026
We propose InfoUtil, a principled dataset distillation framework that formalizes informativeness and utility, leveraging Shapley value attribution and gradient-norm-based selection to synthesize compact yet highly effective datasets, achieving consistent SOTA performance and efficiency across architectures and benchmarks.
FastCar: Cache Attentive Replay for Fast Auto-Regressive Video Generation on the Edge
Xuan Shen, Weize Ma, Yufa Zhou, Enhao Tang, Yanyue Xie, Zhengang Li, Yifan Gong, Quanyi Wang, Henghui Ding, Yiwei Wang, Pu Zhao, Jun Lin, Jiuxiang Gu
ICLR 2026
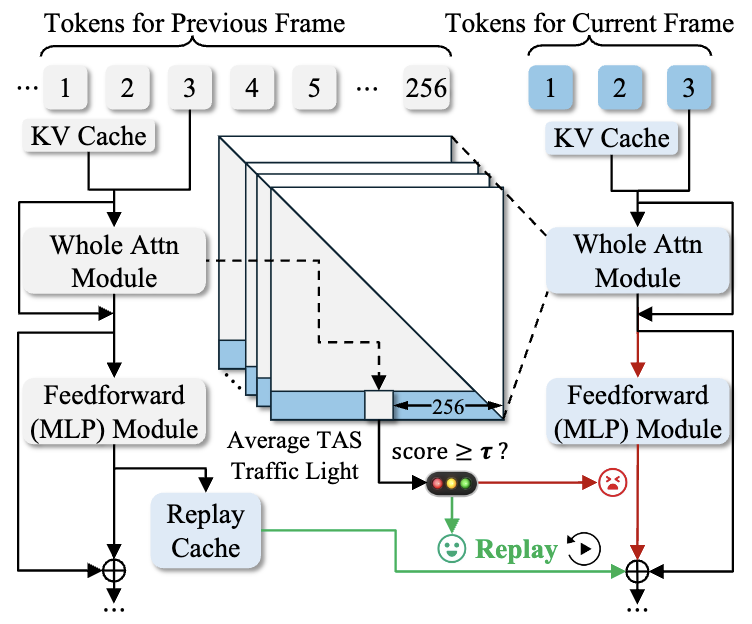
We propose FastCar, a unified framework that accelerates auto-regressive video generation by exploiting temporal redundancy through a Temporal Attention Score for selective computation reuse, integrating with sparse attention and dynamic scheduling to enable real-time, high-resolution synthesis with over 2.1× speedup and minimal quality loss.
FastCar: Cache Attentive Replay for Fast Auto-Regressive Video Generation on the Edge
Xuan Shen, Weize Ma, Yufa Zhou, Enhao Tang, Yanyue Xie, Zhengang Li, Yifan Gong, Quanyi Wang, Henghui Ding, Yiwei Wang, Pu Zhao, Jun Lin, Jiuxiang Gu
ICLR 2026
We propose FastCar, a unified framework that accelerates auto-regressive video generation by exploiting temporal redundancy through a Temporal Attention Score for selective computation reuse, integrating with sparse attention and dynamic scheduling to enable real-time, high-resolution synthesis with over 2.1× speedup and minimal quality loss.
The Geometry of Reasoning: Flowing Logics in Representation Space
Yufa Zhou*, Yixiao Wang*, Xunjian Yin*, Shuyan Zhou, Anru R. Zhang(* equal contribution)
ICLR 2026
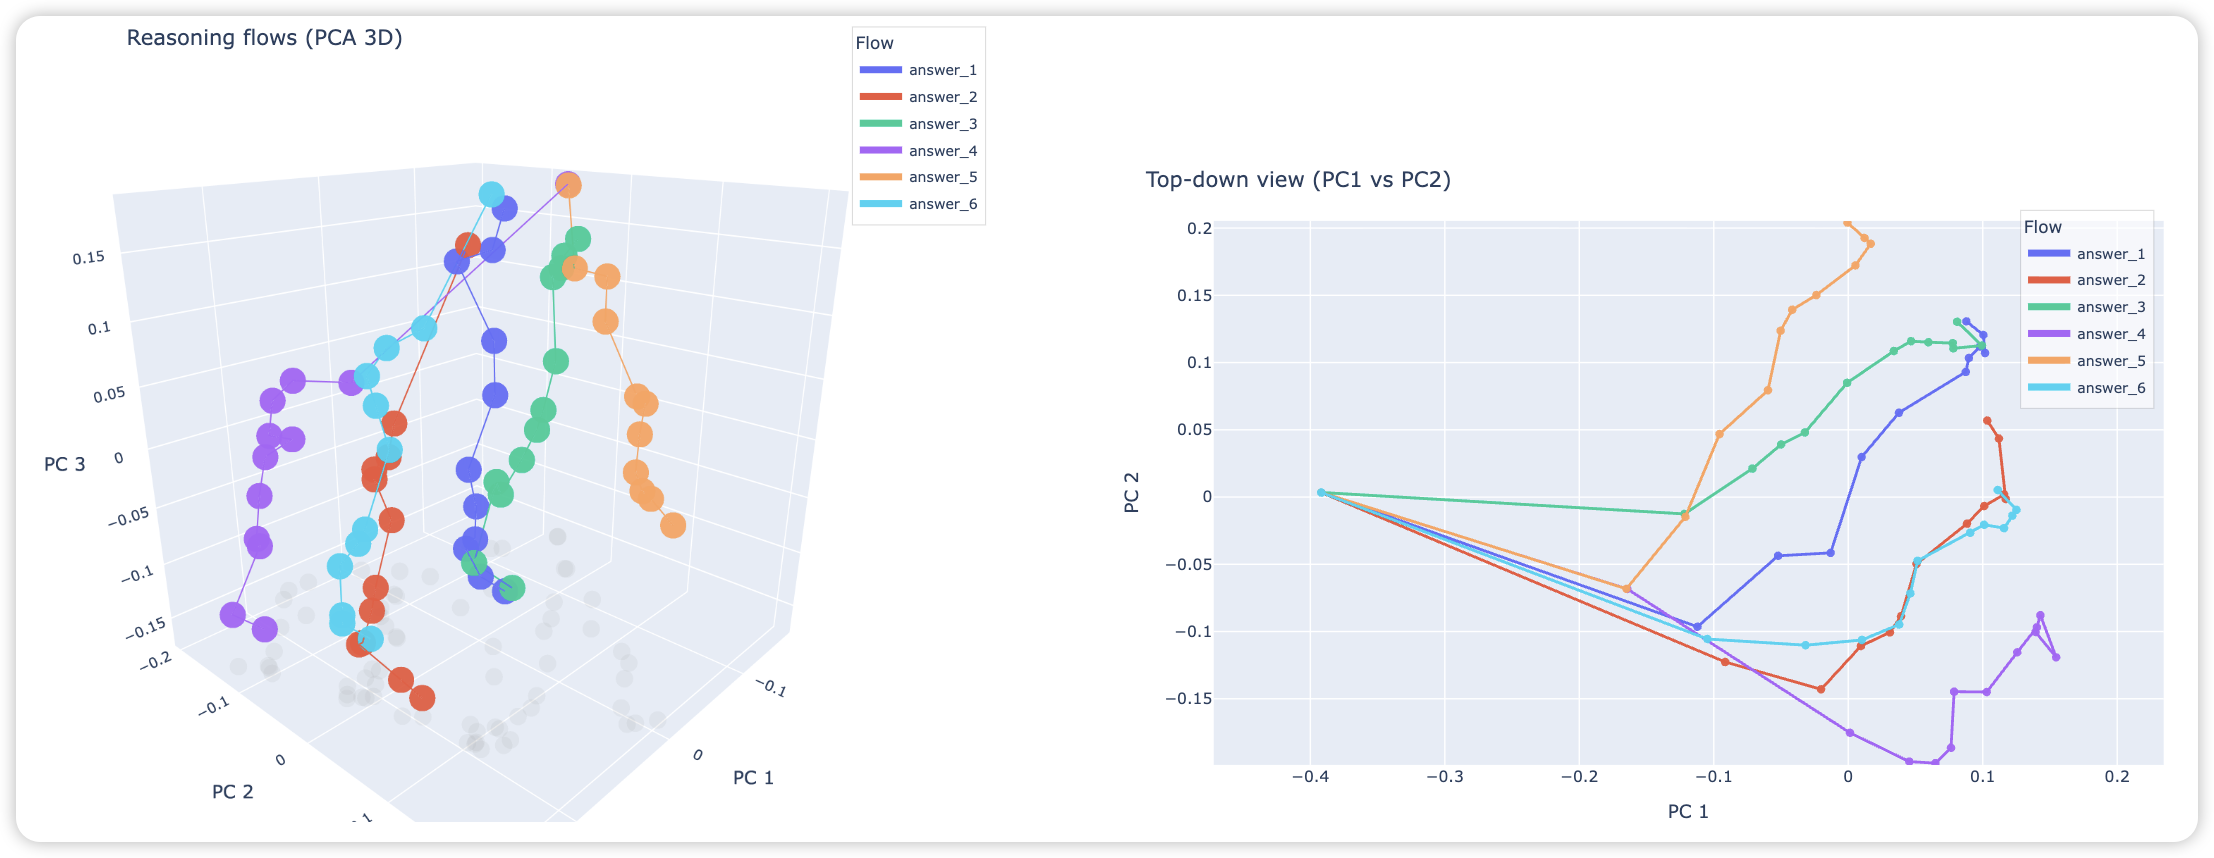
We study how LLMs “think” through their embeddings by introducing a geometric framework of reasoning flows, where reasoning emerges as smooth trajectories in representation space whose velocity and curvature are governed by logical structure rather than surface semantics, validated through cross-topic and cross-language experiments, opening a new lens for interpretability.
The Geometry of Reasoning: Flowing Logics in Representation Space
Yufa Zhou*, Yixiao Wang*, Xunjian Yin*, Shuyan Zhou, Anru R. Zhang(* equal contribution)
ICLR 2026
We study how LLMs “think” through their embeddings by introducing a geometric framework of reasoning flows, where reasoning emerges as smooth trajectories in representation space whose velocity and curvature are governed by logical structure rather than surface semantics, validated through cross-topic and cross-language experiments, opening a new lens for interpretability.
2025
Why Do Transformers Fail to Forecast Time Series In-Context?
Yufa Zhou*, Yixiao Wang*, Surbhi Goel, Anru R. Zhang(* equal contribution)
NeurIPS 2025 Workshop: What Can('t) Transformers Do? Oral (3/68 ≈ 4.4%)
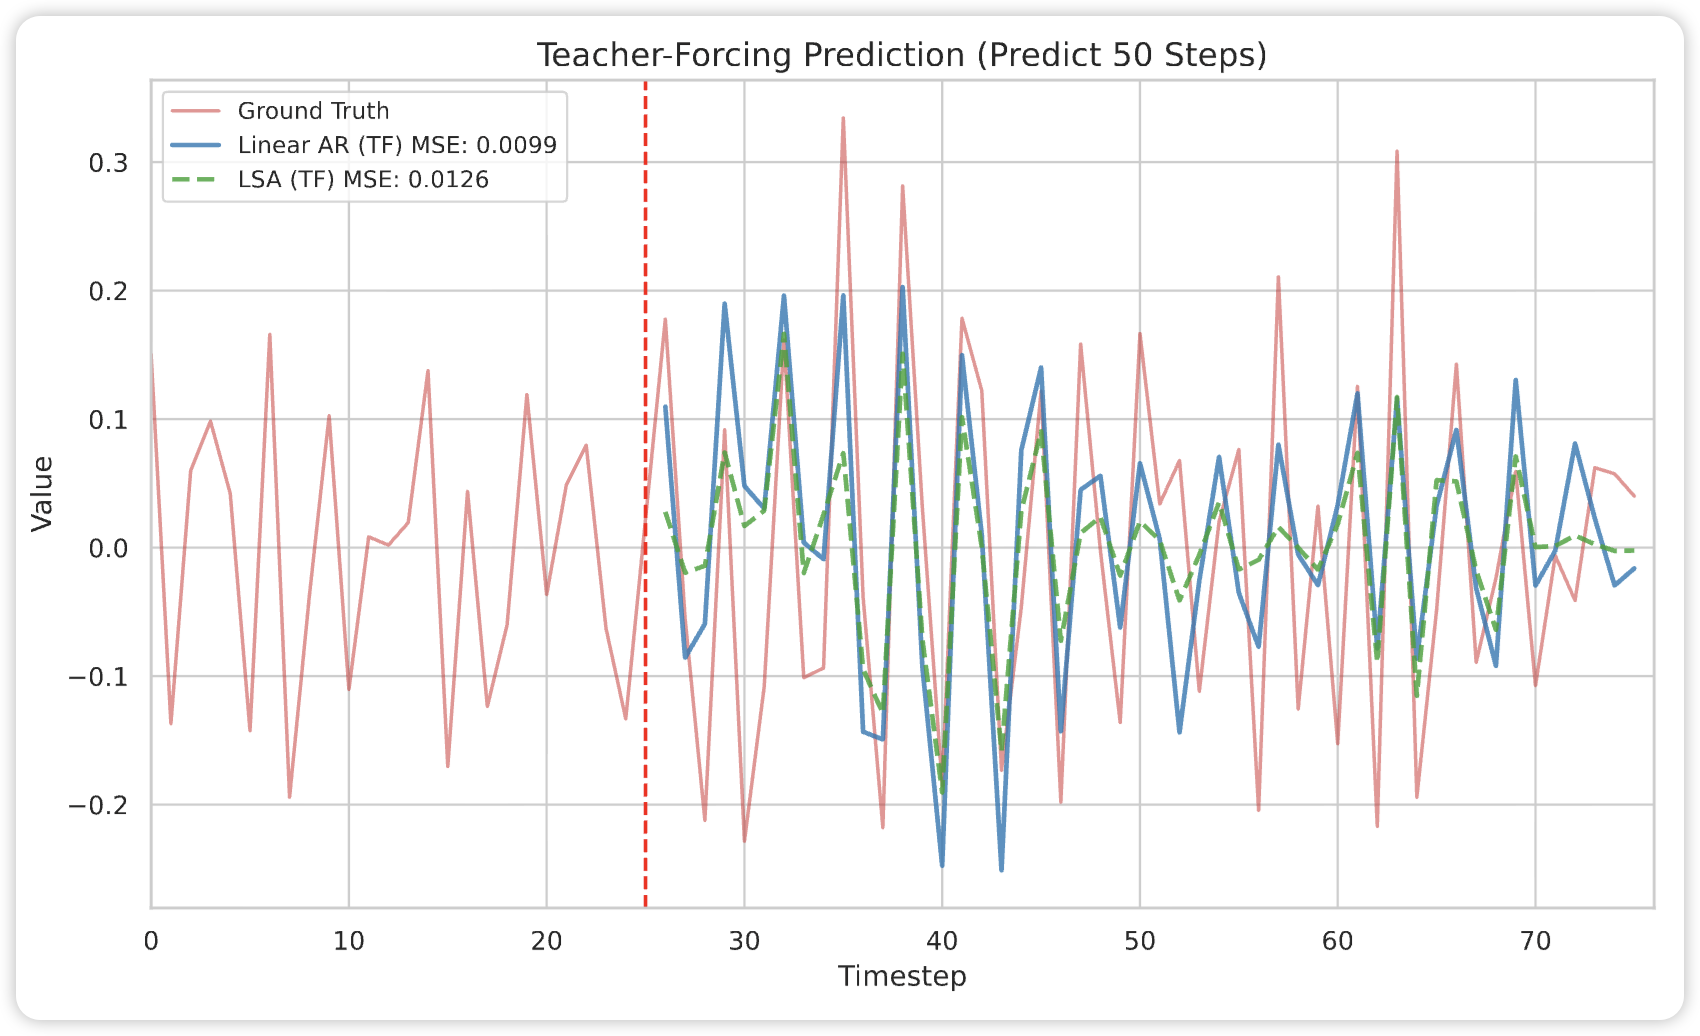
We analyze why Transformers fail in time-series forecasting through in-context learning theory, proving that, under AR($p$) data, linear self-attention cannot outperform classical linear predictors and suffers a strict $O(1/n)$ excess-risk gap, while chain-of-thought inference compounds errors exponentially—revealing fundamental representational limits of attention and offering principled insights.
Why Do Transformers Fail to Forecast Time Series In-Context?
Yufa Zhou*, Yixiao Wang*, Surbhi Goel, Anru R. Zhang(* equal contribution)
NeurIPS 2025 Workshop: What Can('t) Transformers Do? Oral (3/68 ≈ 4.4%)
We analyze why Transformers fail in time-series forecasting through in-context learning theory, proving that, under AR($p$) data, linear self-attention cannot outperform classical linear predictors and suffers a strict $O(1/n)$ excess-risk gap, while chain-of-thought inference compounds errors exponentially—revealing fundamental representational limits of attention and offering principled insights.
Efficient Multi-modal Large Language Models via Progressive Consistency Distillation
Zichen Wen, Shaobo Wang, Yufa Zhou, Junyuan Zhang, Qintong Zhang, Yifeng Gao, Zhaorun Chen, Bin Wang, Weijia Li, Conghui He, Linfeng Zhang
NeurIPS 2025
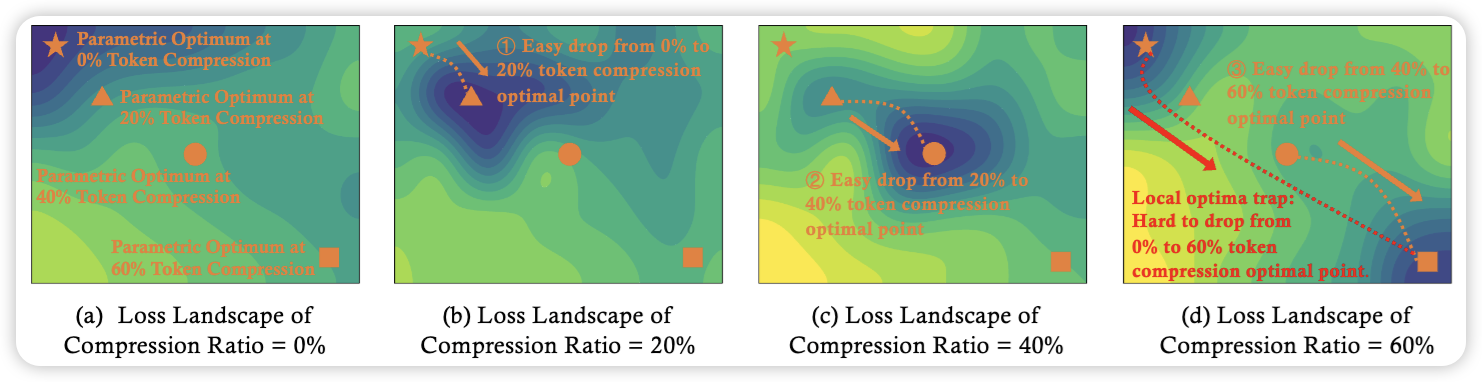
We propose EPIC, a progressive consistency distillation framework that mitigates the training difficulty of token compression in multi-modal LLMs by enforcing token- and layer-level consistency, achieving superior efficiency, robustness, and generalization across benchmarks.
Efficient Multi-modal Large Language Models via Progressive Consistency Distillation
Zichen Wen, Shaobo Wang, Yufa Zhou, Junyuan Zhang, Qintong Zhang, Yifeng Gao, Zhaorun Chen, Bin Wang, Weijia Li, Conghui He, Linfeng Zhang
NeurIPS 2025
We propose EPIC, a progressive consistency distillation framework that mitigates the training difficulty of token compression in multi-modal LLMs by enforcing token- and layer-level consistency, achieving superior efficiency, robustness, and generalization across benchmarks.
Unraveling the Smoothness Properties of Diffusion Models: A Gaussian Mixture Perspective
Yingyu Liang*, Zhizhou Sha*, Zhenmei Shi*, Zhao Song*, Mingda Wan*, Yufa Zhou*(α–β alphabetical order)
ICCV 2025
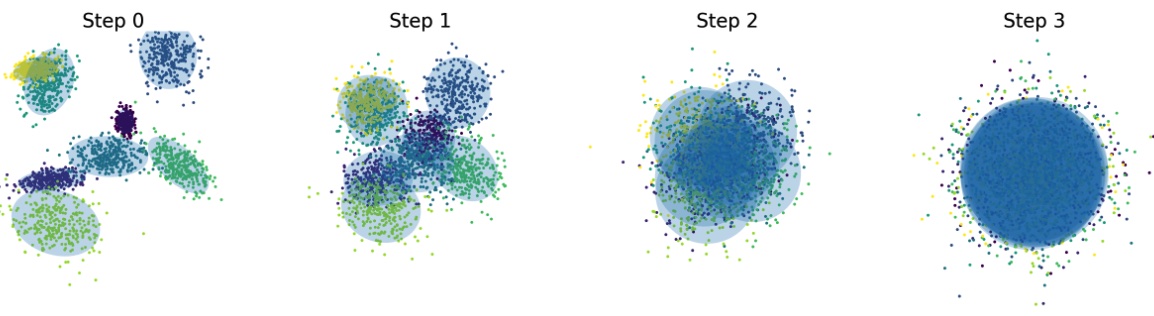
We provide a theoretical analysis showing that for diffusion models with Gaussian mixture data, the diffusion process preserves the mixture structure; we derive tight, component-independent bounds on Lipschitz constants and second moments, and establish error guarantees for diffusion solvers—offering deeper insights into the diffusion dynamics under common data distributions.
Unraveling the Smoothness Properties of Diffusion Models: A Gaussian Mixture Perspective
Yingyu Liang*, Zhizhou Sha*, Zhenmei Shi*, Zhao Song*, Mingda Wan*, Yufa Zhou*(α–β alphabetical order)
ICCV 2025
We provide a theoretical analysis showing that for diffusion models with Gaussian mixture data, the diffusion process preserves the mixture structure; we derive tight, component-independent bounds on Lipschitz constants and second moments, and establish error guarantees for diffusion solvers—offering deeper insights into the diffusion dynamics under common data distributions.
DraftAttention: Fast Video Diffusion via Low-Resolution Attention Guidance
Xuan Shen*, Chenxia Han*, Yufa Zhou*, Yanyue Xie, Yifan Gong, Quanyi Wang, Yiwei Wang, Yanzhi Wang, Pu Zhao, Jiuxiang Gu(* equal contribution)
arXiv 2025
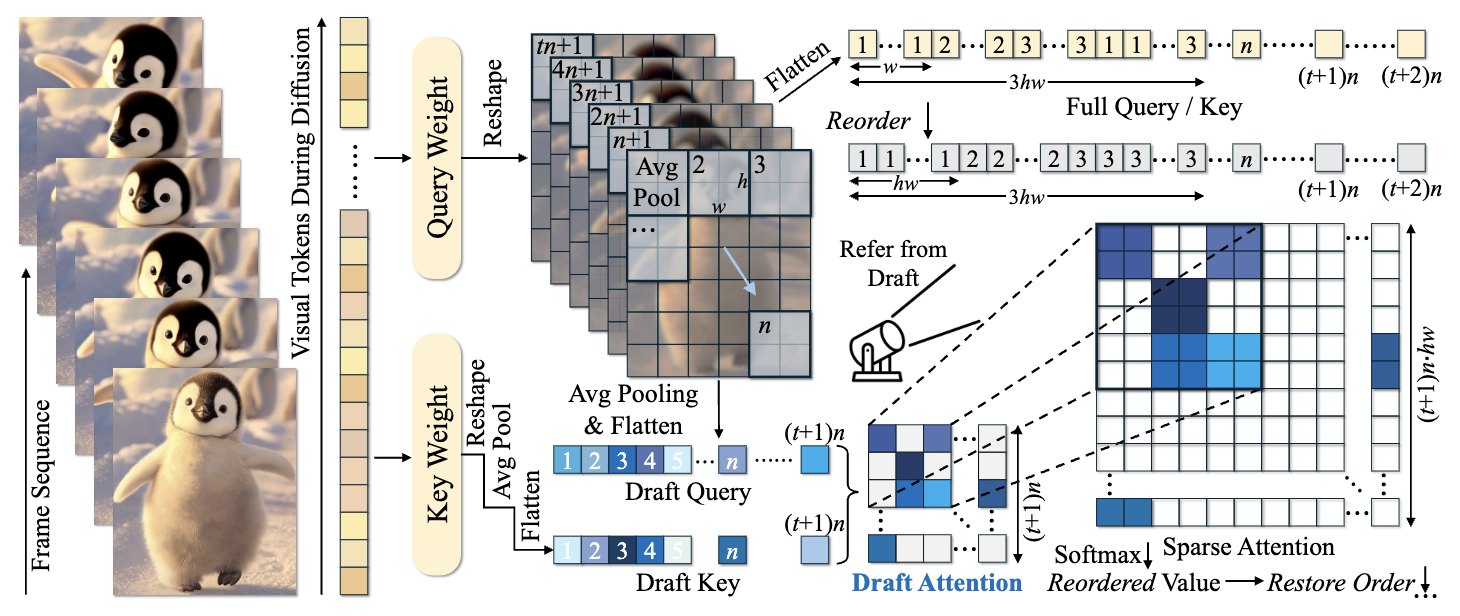
We propose DraftAttention, a method that accelerates video diffusion transformers by leveraging low-resolution pooled attention maps to enable dynamic sparse attention and hardware-efficient execution, achieving up to 1.75× speedup with minimal quality loss.
DraftAttention: Fast Video Diffusion via Low-Resolution Attention Guidance
Xuan Shen*, Chenxia Han*, Yufa Zhou*, Yanyue Xie, Yifan Gong, Quanyi Wang, Yiwei Wang, Yanzhi Wang, Pu Zhao, Jiuxiang Gu(* equal contribution)
arXiv 2025
We propose DraftAttention, a method that accelerates video diffusion transformers by leveraging low-resolution pooled attention maps to enable dynamic sparse attention and hardware-efficient execution, achieving up to 1.75× speedup with minimal quality loss.
Looped ReLU MLPs May Be All You Need as Practical Programmable Computers
Yingyu Liang*, Zhizhou Sha*, Zhenmei Shi*, Zhao Song*, Yufa Zhou*(α–β alphabetical order)
AISTATS 2025
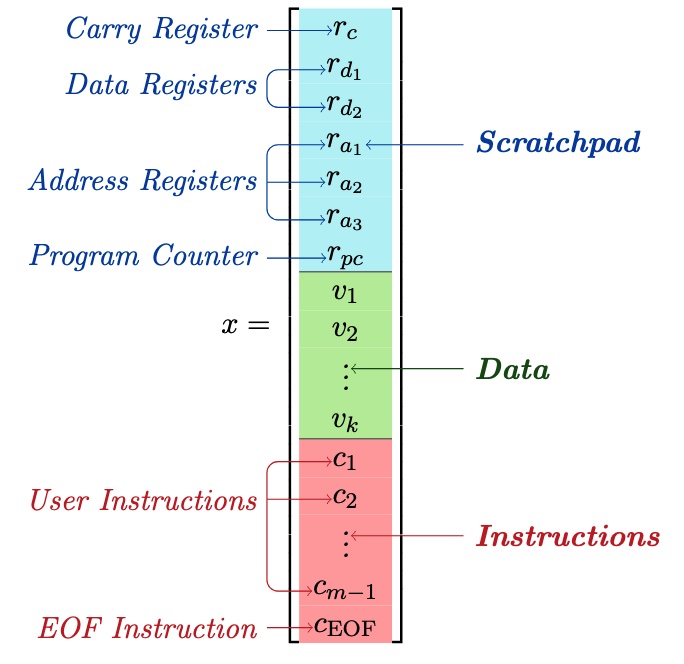
We demonstrate that a looped 23-layer ReLU-MLP can function as a universal programmable computer—revealing that simple neural network modules possess greater expressive power than previously thought and can perform complex tasks without relying on advanced architectures like Transformers.
Looped ReLU MLPs May Be All You Need as Practical Programmable Computers
Yingyu Liang*, Zhizhou Sha*, Zhenmei Shi*, Zhao Song*, Yufa Zhou*(α–β alphabetical order)
AISTATS 2025
We demonstrate that a looped 23-layer ReLU-MLP can function as a universal programmable computer—revealing that simple neural network modules possess greater expressive power than previously thought and can perform complex tasks without relying on advanced architectures like Transformers.
Beyond Linear Approximations: A Novel Pruning Approach for Attention Matrix
Yingyu Liang*, Jiangxuan Long*, Zhenmei Shi*, Zhao Song*, Yufa Zhou*(α–β alphabetical order)
ICLR 2025
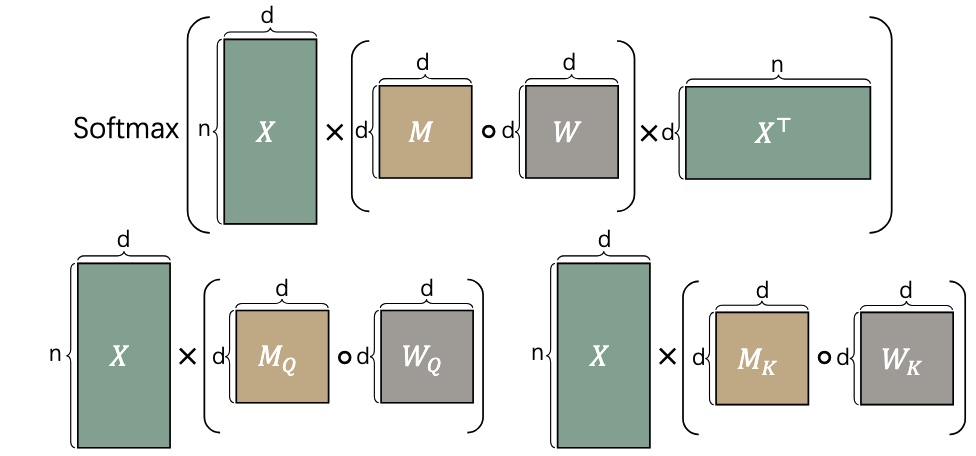
We introduce a novel LLM weight pruning method that directly optimizes for approximating the non-linear attention matrix—with theoretical convergence guarantees—effectively reducing computational costs while maintaining model performance.
Beyond Linear Approximations: A Novel Pruning Approach for Attention Matrix
Yingyu Liang*, Jiangxuan Long*, Zhenmei Shi*, Zhao Song*, Yufa Zhou*(α–β alphabetical order)
ICLR 2025
We introduce a novel LLM weight pruning method that directly optimizes for approximating the non-linear attention matrix—with theoretical convergence guarantees—effectively reducing computational costs while maintaining model performance.
Numerical Pruning for Efficient Autoregressive Models
Xuan Shen, Zhao Song, Yufa Zhou, Bo Chen, Jing Liu, Ruiyi Zhang, Ryan A. Rossi, Hao Tan, Tong Yu, Xiang Chen, Yufan Zhou, Tong Sun, Pu Zhao, Yanzhi Wang, Jiuxiang Gu
AAAI 2025
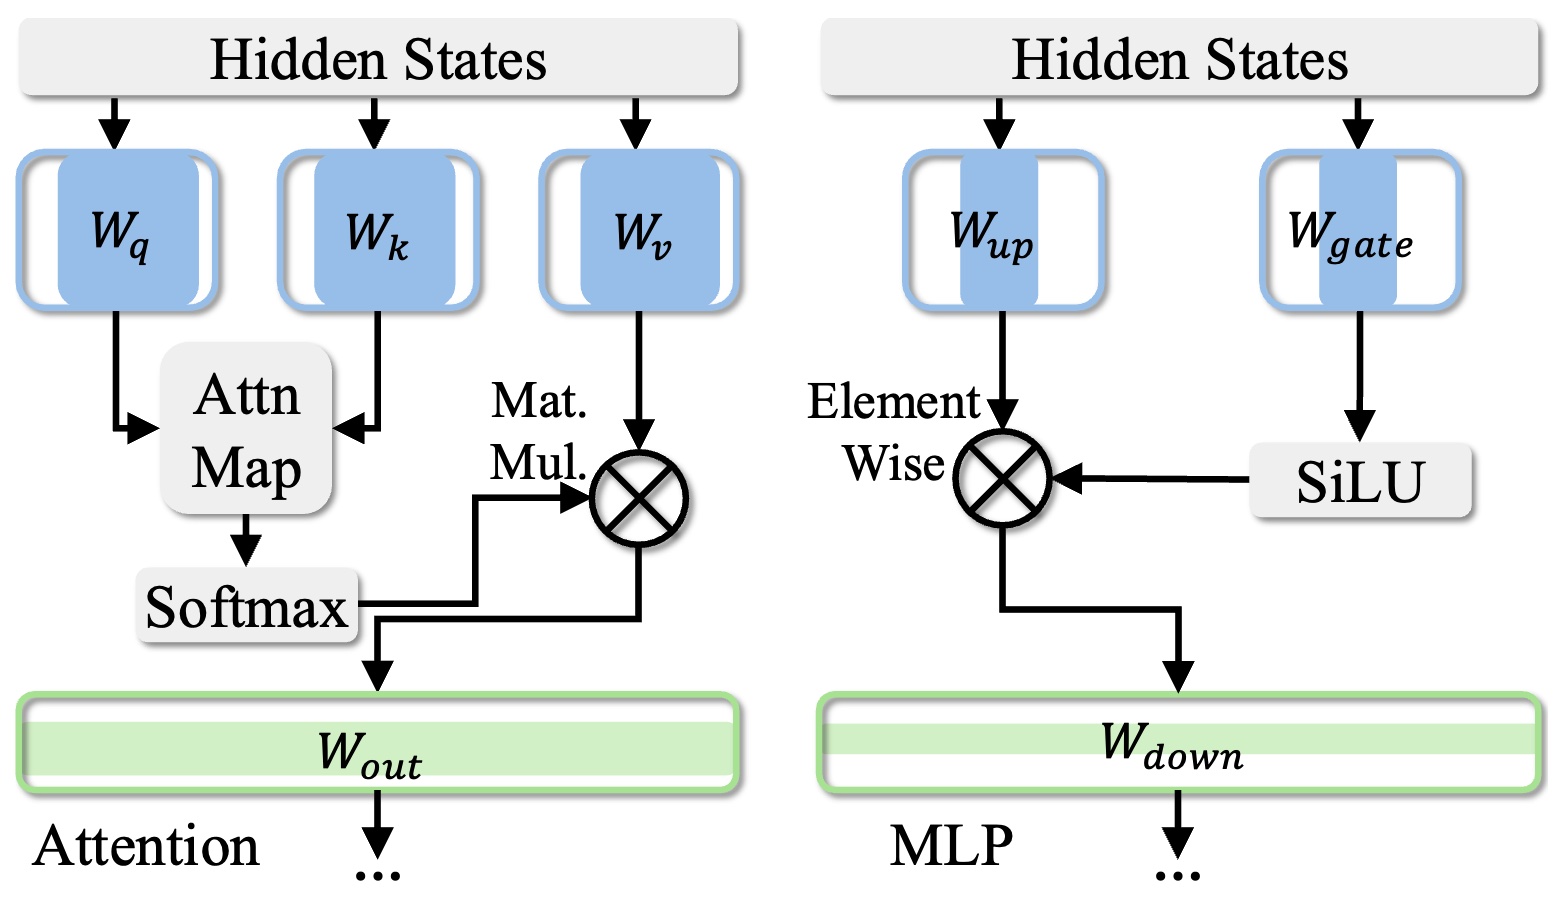
We present a training-free structural pruning method using Newton’s method and compensation algorithms to efficiently compress decoder-only transformer models, achieving state-of-the-art performance with reduced memory usage and faster generation on GPUs.
Numerical Pruning for Efficient Autoregressive Models
Xuan Shen, Zhao Song, Yufa Zhou, Bo Chen, Jing Liu, Ruiyi Zhang, Ryan A. Rossi, Hao Tan, Tong Yu, Xiang Chen, Yufan Zhou, Tong Sun, Pu Zhao, Yanzhi Wang, Jiuxiang Gu
AAAI 2025
We present a training-free structural pruning method using Newton’s method and compensation algorithms to efficiently compress decoder-only transformer models, achieving state-of-the-art performance with reduced memory usage and faster generation on GPUs.
LazyDiT: Lazy Learning for the Acceleration of Diffusion Transformers
Xuan Shen, Zhao Song, Yufa Zhou, Bo Chen, Yanyu Li, Yifan Gong, Kai Zhang, Hao Tan, Jason Kuen, Henghui Ding, Zhihao Shu, Wei Niu, Pu Zhao, Yanzhi Wang, Jiuxiang Gu
AAAI 2025
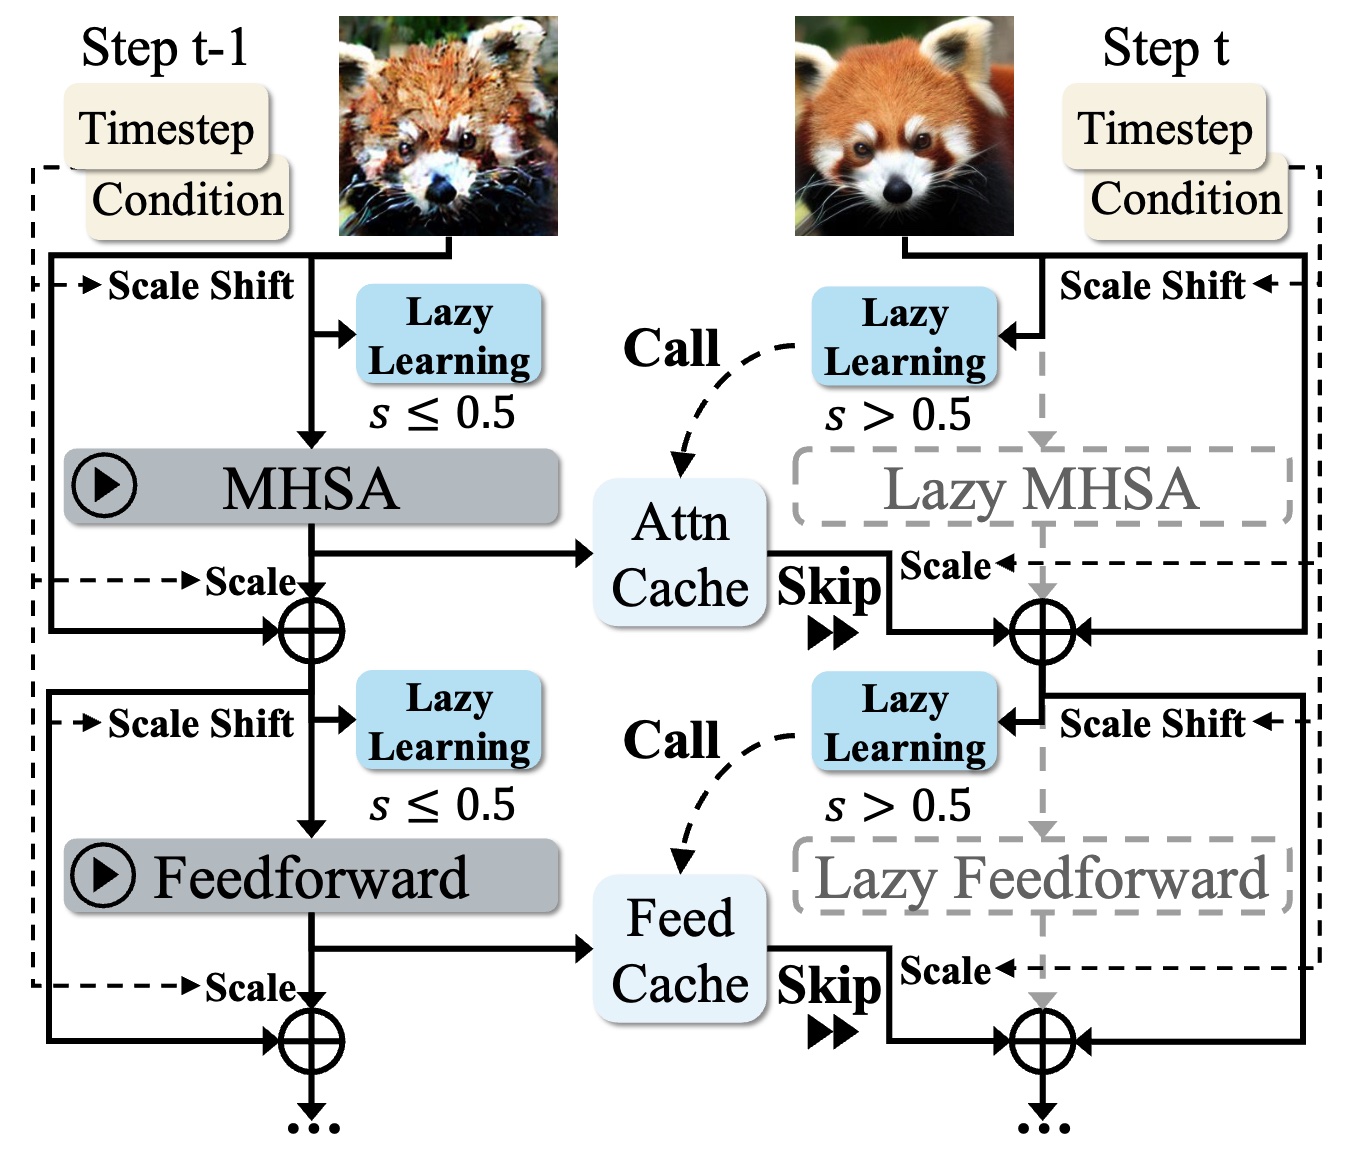
We present LazyDiT, a framework that accelerates Diffusion Transformers by reusing computations from previous steps and dynamically skipping redundancies, achieving superior performance over existing methods like DDIM across multiple models and devices.
LazyDiT: Lazy Learning for the Acceleration of Diffusion Transformers
Xuan Shen, Zhao Song, Yufa Zhou, Bo Chen, Yanyu Li, Yifan Gong, Kai Zhang, Hao Tan, Jason Kuen, Henghui Ding, Zhihao Shu, Wei Niu, Pu Zhao, Yanzhi Wang, Jiuxiang Gu
AAAI 2025
We present LazyDiT, a framework that accelerates Diffusion Transformers by reusing computations from previous steps and dynamically skipping redundancies, achieving superior performance over existing methods like DDIM across multiple models and devices.